
The world starts to expand.
Overwrld is a data capacity engine via AI compression and data infrastructure — a portable lossless compressor with cheap decode. We reached #1 on August 30, 2026 on the field's hardest public benchmark. Less data moved means less infrastructure required, and the saving compounds across storage, bandwidth, compute and energy.
We believe the most exciting worlds are the ones waiting to be discovered.
Data is exploding. Moving it is expensive.
Every AI workload, video stream, cloud application and data center pays the same tax, and it is charged four times over.
Storage × Bandwidth × Compute × Energy
Same bytes. Four invoices. The bill compounds.
Less data moved = Less infrastructure required
The industry's answer has been to build more: more racks, more fiber, more power. Compression is the only lever that makes what already exists carry more — the doorway through which the next world of capacity opens.
We reached #1 on August 30.
Two proofs, kept separate. The engine reached #1 on August 30, 2026 on Matt Mahoney's Large Text Compression Benchmark. The product is a portable binary that keeps most of the ratio and makes decode cheap enough to ship.
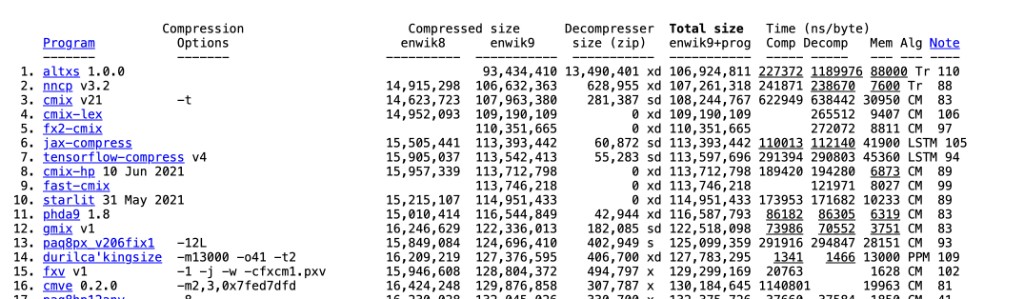
Bars are zero-based and scaled to the largest total on this chart. Official ranking is by total size. Payload is shown for context.
- Public rank
- #1
- Reached
- Aug 30
- Payload
- 93.4 MB
- Total S
- 106.9 MB
We reached #1 on August 30, 2026 with altxs 1.0.0, by official total size — payload plus decompressor. That is the number a partner will check. The board is below.
| System | Corpus | Bytes | Source |
|---|---|---|---|
| Overwrld altxs 1.0.0 | enwik9, payload + decompressor | 106,924,811 | ranked #1 August 30, 2026 |
| nncp v3.2 | enwik9, total S | 107,261,318 | LTCB, as of August 30, 2026 |
| Overwrld altxs 1.0.0 | enwik9, payload | 93,434,410 | same public row |
Benchmark: Large Text Compression Benchmark (enwik9), lossless, decompressor counted. Program altxs 1.0.0. We reached #1 on August 30, 2026 by official total-size ranking. Payload 93,434,410 + decompressor 13,490,401 = 106,924,811 total. The 91.7 MB figure is a later model, not on the board, and is not the rank.
How each of these numbers is counted · Open the public board
Video first. Then the data center.
The engine is domain-general. The order we take markets in is not. We start where the bytes are densest and the decoder is ours to place.
Video
The largest volume of bytes in motion, and the clearest economics. Every increase in resolution or frame rate is paid for in bandwidth, and the codecs that carry it are frozen standards.
AI infrastructure
Data centers are constrained by power, interconnect and floor space, not by ambition. Moving less data between clusters is capacity you do not have to build.
And the data that is already waiting for this
Cold and archival storage, mezzanine and contribution feeds, and write-once high-value data all fit the shape of the engine today: spend the compute once at encode, keep reading cheap forever.
Three ways to spend compute and buy bytes back.
Most compression products give you one setting. We choose the mode from what the asset is worth, because a cold archive read twice a year justifies compute that a live cache never will.
- 01One model, many kinds of dataAmortized across domains
- 02Specialised to a single assetClosest to that file's floor
- 03Search, then verifyHighest value data only
The lead compounds.
A standard is frozen the day it ships. AV1 is frozen. AV2 will be frozen. Ours isn't.
It improves after you buy it
Next year's version beats the one you signed for. No new standard, no hardware swap, no migration.
It specializes
Tuned to each customer's own data, not the compromise a global standard must pick for everyone at once.
The lead is defensible
A competitor cannot fork a moving target. Catching us means catching a system that keeps moving, not out-engineering one release.
The record is the proof. The product is the opportunity.
- 01Technical moatA public, named result on the field's hardest open benchmark, and an architecture that keeps improving after release — in a field where every standard is frozen the day it ships.
- 02Commercial productPortable compression binary designed to capture most of the breakthrough's benefit at a decode cost cheap enough to ship.
- 03Massive customersStreaming and media, then cloud, then AI infrastructure, then enterprise data.
- 04Business modelUsage-based infrastructure. Enterprise license plus usage.
Built data and sales where the bytes already hurt.
The people shipping Overwrld have built data systems and enterprise sales across OpenAI, 84.51°, Databricks, and Amazon — the rooms where compression, capacity, and a closed deal are the same problem.
- OpenAI
- 84.51°
- Databricks
- Amazon
Conrad Lippert-Zajaczkowski
Founder. Listed author of altxs on the public Large Text Compression Benchmark.
D'Angelo Oberto-Besso Pando
Operations. Keeps the company pointed at shipping, not slides.
Will Simpson
Product. Turns a benchmark engine into something a buyer can place.
Brittany Dao
Enterprise sales. Fortune 500 closes including $33M CVS/Aetna at Adobe.
Hoon
Core build. The binary has to land in a customer's stack, not a lab.
Josh
AI/ML and data quality. The engine is only as honest as the data it is measured on.
Samantha Vidal
Fractional counsel. Commercial and corporate work as the company takes on customers.
The team has closed or supported $180M+ in enterprise revenue. Brittany closed $98M in Fortune 500 deals, including $33M for CVS/Aetna at Adobe.
All that's left to do is step forward.
The fastest way to find out whether this pays off for you is to measure it on your own corpus, against your own tuned baseline.